Test Post from Pipeline

“`html
<article class="post-content">
<h1>How Google Search Ranking Actually Works in 2026</h1>

<p>By <strong>Kyle Brennan</strong></p>

<p>Every year, someone publishes a take on "how Google ranking works" that reads like it was written in 2019 and updated with a find-and-replace. That approach has never worked well, and it especially doesn't work now. Google's search systems have shifted enough since the early 2020s that pretending otherwise is just bad analysis. So let's walk through what is actually happening when a page ranks—or doesn't—in 2026.</p>

<img src="https://images.pexels.com/photos/3184291/pexels-photo-3184291.jpeg?auto=compress&cs=tinysrgb&w=1260" alt="Data visualization on monitors representing search ranking analysis" />

<h2>The Big Picture: What Google Is Trying to Do</h2>

<p>Google's core objective has not changed: return results that satisfy the searcher's intent quickly and credibly. What has changed is how effectively Google can measure whether a page actually does that. The systems are better at parsing meaning, better at evaluating source credibility, and far less forgiving of the mechanical tricks that used to work.</p>

<p>If you strip away the jargon, Google ranking in 2026 comes down to three questions:</p>

<ul>
<li>Does this page answer the query?</li>
<li>Is the source trustworthy?</li>
<li>Is the experience of consuming this page good?</li>
</ul>

<p>Everything else is a subcategory of one of those three. Let's break each one down.</p>

<h2>Does This Page Answer the Query?</h2>

<h3>Relevance and Intent Matching</h3>

<p>Google has gotten significantly better at understanding what a query means, not just what words it contains. A search for "best budget laptop for college 2026" has a clear intent: the searcher wants a recommendation, not a textbook on laptop architecture. Google's language models parse that intent and match it against pages that actually deliver recommendations, comparisons, and specific product names—not just pages that happen to contain those keywords.</p>

<p>Keyword frequency still plays a role, but it's a minor one. What matters more is whether the content addresses the full scope of what someone with that query would need to know. For the laptop example, that means covering price ranges, performance benchmarks, battery life, and build quality. Thin content that repeats the keyword without substantive coverage simply does not rank.</p>

<h3>Topical Authority</h3>

<p>Google also considers whether your site has a track record of covering a topic. A site that publishes one article about laptops and fifty about gardening will struggle to rank for laptop queries, regardless of how well-written that single article is. This is what the SEO industry calls topical authority, and by 2026 it is a clear, measurable ranking factor.</p>

<p>The mechanism is straightforward: Google's systems associate your domain with clusters of topics based on your content history and how other reputable sources link to you. If you want to rank for a new topic area, you need to build out enough content that Google starts treating your site as a meaningful source on that subject. One-off pages rarely break through anymore.</p>

<h2>Is the Source Trustworthy?</h2>

<img src="https://images.pexels.com/photos/3184460/pexels-photo-3184460.jpeg?auto=compress&cs=tinysrgb&w=1260" alt="Team collaborating on content credibility assessment" />

<h3>E-E-A-T in Practice</h3>

<p>Google's E-E-A-T framework—Experience, Expertise, Authoritativeness, Trustworthiness—has been around for years, but its influence has grown substantially. By 2026, it is not just a guideline for quality raters; it is deeply embedded in how ranking systems evaluate pages, particularly for what Google calls YMYL (Your Money or Your Life) topics: health, finance, safety, legal matters.</p>

<p>What does E-E-A-T actually mean in practice? It means Google looks for signals that the person writing the content has legitimate standing. For a medical article, that means credentials, cited research, and links from other medical authorities. For a product review, it means evidence that the author actually tested the product—photos, specific observations, methodology details.</p>

<p>Anonymous or pseudonymous content is not disqualified outright, but it faces a steeper climb. If Google cannot verify who created a piece of content and whether they have relevant experience, the page will generally rank below content where those signals are clear.</p>

<h3>Link-Based Authority Still Matters</h3>

<p>Links from other sites remain one of the strongest signals Google uses to assess authority. The basic logic has not changed: if many credible sites link to you, you are probably credible. But the definition of "credible" has tightened. A link from the New York Times carries more weight than a link from a random blog that nobody reads. And links from sites Google identifies as part of private blog networks or link schemes are effectively worthless—or worse, they can drag your site down.</p>

<p>The best approach to links in 2026 is the same as it was in 2016: earn them by publishing content that other people genuinely want to reference. Outreach campaigns and link exchanges still happen, but their return on investment continues to shrink as Google gets better at discounting manufactured links.</p>

<h2>Is the Experience Good?</h2>

<h3>Core Web Vitals and Technical Performance</h3>

<p>Google's Core Web Vitals—Largest Contentful Paint (LCP), Interaction to Next Paint (INP), and Cumulative Layout Shift (CLS)—remain the primary technical performance signals. In 2026, the bar is higher. Most competitive sites have already optimized for these metrics, so simply meeting the baseline no longer gives you an advantage. But failing them will absolutely hurt you.</p>

<p>LCP should be under 2.5 seconds. INP should be under 200 milliseconds. CLS should be under 0.1. If your site misses these targets, Google interprets that as a poor user experience and ranks you accordingly. The fix is usually technical: better hosting, optimized images, efficient JavaScript loading, proper font handling. None of this is glamorous, but it is table stakes.</p>

<h3>Mobile-First Is Fully Default</h3>

<p>Google indexes the mobile version of your site first. This has been true since 2020, but by 2026 the mobile-first index is effectively the only index for most sites. If your mobile experience is a degraded version of your desktop site, you are actively losing rankings. Responsive design, touch-friendly navigation, and fast mobile load times are not optional features—they are foundational requirements.</p>

<h3>Interstitials and Intrusive Elements</h3>

<p>Google continues to penalize pages that block content with intrusive pop-ups, interstitials, or ads that make the page difficult to use. A full-screen newsletter popup on mobile load, a massive ad that pushes content below the fold, a cookie consent banner that covers half the screen—these all contribute to a degraded experience, and Google's systems account for that in rankings.</p>

<h2>What Actually Moves the Needle</h2>

<img src="https://images.pexels.com/photos/3184303/pexels-photo-3184303.jpeg?auto=compress&cs=tinysrgb&w=1260" alt="Analytics dashboard showing search performance metrics" />

<p>With all of that context, here is what actually makes a difference when you are trying to improve rankings in 2026:</p>

<ol>
<li><strong>Publish content that fully answers the query.</strong> Not partially. Not with a keyword-stuffed introduction that buries the useful information. Fully. If someone searches "how to fix a leaky faucet," give them step-by-step instructions with clear details. Do not make them click through to another page.</li>
<li><strong>Demonstrate real expertise.</strong> Use author bios. Cite primary sources. Include original data, original images, or original testing where applicable. If you are writing about a product you have never touched, Google's systems—and users—can tell.</li>
<li><strong>Build genuine authority over time.</strong> Cover a topic area deeply enough that your site becomes a recognized resource. This takes months, not days. It requires consistent publishing of substantive content in a focused niche.</li>
<li><strong>Fix your technical fundamentals.</strong> Make your site fast, mobile-friendly, and free of intrusive elements. This alone will not push you to page one, but neglecting it will hold you back regardless of how good your content is.</li>
<li><strong>Earn links from real sources.</strong> Create content that journalists, educators, and industry professionals actually want to cite. This is harder than buying links, but it is the only approach that compounds over time.</li>
</ol>

<h2>Common Misconceptions in 2026</h2>

<h3>"Google penalizes sites for using AI-generated content."</h3>

<p>This is wrong, and Google has said so explicitly. Google does not care how content was created. It cares whether the content is helpful, accurate, and trustworthy. A well-researched, clearly written article is valuable regardless of the tools used to produce it. What Google penalizes is low-effort, unoriginal, or misleading content—regardless of its origin.</p>

<h3>"Backlinks don't matter anymore."</h3>

<p>Also wrong. Links remain one of the strongest off-page ranking signals. What has changed is that low-quality links matter less than they used to, and Google is much better at ignoring or discounting manipulative link patterns. If your link profile is built on genuine citations from credible sources, it still provides a significant ranking advantage.</p>

<h3>"Publishing more frequently improves rankings."</h3>

<p>Frequency itself is not a ranking factor. Publishing ten mediocre articles per week will not help you rank. Publishing one excellent article per week might. What matters is the quality and helpfulness of each piece of content, not the cadence of publication. Google has explicitly confirmed this.</p>

<p>For additional context on Google's own ranking guidance, their <a href="https://developers.google.com/search/docs/fundamentals/creating-helpful-info" target="_blank" rel="noopener">documentation on creating helpful content</a> and <a href="https://developers.google.com/search/docs/fundamentals/seo-starter-guide" target="_blank" rel="noopener">SEO starter guide</a> remain the most authoritative sources available.</p>

<h2>FAQ</h2>

<h3>How long does it take for a new page to rank on Google?</h3>

<p>Most new pages start appearing in search results within a few days to a few weeks, but reaching their final ranking position typically takes two to six months. Google's systems need time to evaluate how users interact with a page, how it accumulates links, and whether it satisfies search intent relative to competing pages. New domains or pages covering topics where the site has no established authority will take longer.</p>

<h3>Does Google still use the PageRank algorithm?</h3>

<p>PageRank as it was originally conceived—the simple link-counting formula from 1998—has been obsolete for many years. However, the concept of using link structures to assess authority is still part of Google's ranking systems. Modern versions are far more sophisticated, incorporating link context, source quality, and link patterns rather than raw link counts.</p>

<h3>Can a small site outrank a large, established competitor?</h3>

<p>Yes, but not by competing on the same terms. Large sites have domain authority and topical breadth that small sites cannot match quickly. Small sites can compete by focusing on very specific niches where they have genuine expertise, creating content that is more detailed and more directly useful than what larger competitors publish, and building real relationships with other credible sources in their field. It takes sustained effort, but it is absolutely possible.</p>

<hr />

<p><em>Kyle Brennan writes about search, engineering, and the mechanics of the web at <a href="https://adgoog.com">adgoog.com</a>.</em></p>
</article>
“`
Continue Reading

Salt Typhoon’s Reckoning: Why Your 2026 Architecture Decisions Matter More Than You Think

The Breach That Changed the Rules

Late 2024 felt like watching a slow-motion car crash play out across nine major US telecommunications carriers. The FBI and CISA confirmed what security researchers had been tracking: Chinese state-sponsored actors, operating under the name Salt Typhoon, had maintained access to networks operated by AT&T, Verizon, and others for over a year. Not months. A year. For anyone who’s ever stared at a compromised system at 3 AM, wondering how deep the infection goes, this hit different.

What made Salt Typhoon particularly unsettling wasn’t the sophistication of some exotic zero-day. It was the opposite. The attackers exploited a greatest-hits compilation of engineering shortcuts that many of us inherited from previous decades: legacy SNMP configurations left in default states, edge devices from Cisco and Fortinet that sat unpatched despite publicly available fixes, and network architectures with essentially no meaningful segmentation between management interfaces and operational systems. The CISA Salt Typhoon advisory laid it out in merciless detail. These weren’t alien attack vectors. They were the exact things we built into systems five, sometimes ten years ago because they worked and because rearchitecting always gets pushed to next quarter.

The Patch That Wasn’t Applied

Here’s where the story gets visceral. Cisco’s CVE-2023-20198 vulnerability in IOS XE received a perfect CVSS score of 10.0, which is as close to “this will end you” as the scoring system gets. The patch was available well over a year before researchers confirmed that Salt Typhoon was actively exploiting it. One year. That’s not a zero-day scramble situation. That’s not even an obscure edge case most organizations miss. That’s a known, scored, patched, high-visibility vulnerability that somehow remained live on critical infrastructure.

I mention this not to shame anyone specific. I mention it because I’ve been that engineer on the conference call explaining why we can’t patch the carrier-grade network management interface during Q4 earnings season. I’ve also been the one cleaning up after that decision backfired badly. The vulnerability sat there like a door someone decided not to lock because the hallway seemed safe. Then someone tried every door, found that one open, and walked through.

The FCC’s New Mandate: Engineering Gets Political

By January 2025, regulatory patience had evaporated. The FCC issued new cybersecurity rules under Section 105 of the Communications Act. For the first time, carriers now face a mandate to submit annual cybersecurity risk management plans. This isn’t guidance. This isn’t best practice documentation. This is regulation with teeth, and it arrives with the clear message that the free-form “we’ll secure what we secure” era is over.

What this means for anyone building or maintaining network-adjacent systems is straightforward but demanding: your architecture now exists within a compliance framework that has legal weight. The FCC cybersecurity rulemaking proceeding documents spell out expectations around segmentation, access controls, and incident reporting. More importantly, they’re forcing a reckoning with the technical debt that companies like AT&T and Verizon are currently paying down in a very public, very expensive way. That debt is now regulatory risk.

If you’re an engineer at a carrier or a vendor building systems for carriers, 2026 isn’t some distant planning horizon. It’s the year your current architecture gets stress-tested against rules that didn’t exist six months ago. The compliance window is real, and it’s compressed.

The Cost of Architectural Reckoning

A Mandiant report released in February 2025 surveyed remediation efforts across organizations affected by Salt Typhoon. The numbers were sobering. Seventy-three percent of affected organizations required complete rearchitecture of their carrier-grade network management interfaces. Not patches. Not configuration fixes. Full rearchitecture. Average remediation costs exceeded $47 million per carrier.

That figure isn’t abstract. It’s engineers, architects, and project managers ripping out systems that worked but shouldn’t have, and replacing them with systems designed for 2025 threat models. Network segmentation implemented properly. Management interfaces isolated behind proper authentication and encryption. The stuff we knew was right but kept deferring because the current setup “worked for now.”

There’s a brutal irony to waiting until something breaks catastrophically before building correctly: you finally get to build correctly, but you’re doing it under regulatory pressure, with auditors watching, and with incident timeline documentation etched into everyone’s calendar. Engineers who start thinking about compliance-driven architecture redesign now are going to have far less chaotic lives than those who treat January 2026 as a starting point.

Signal Versus Speculation: What Actually Changes

Let me be clear about what I’m confident about and what I’m forecasting. The regulatory pressure is signal. The FCC rules exist. The carriers are definitely remediating. That’s all confirmed. What I’m more speculative about is how aggressively smaller carriers and regional players will prioritize compliance. The big names like AT&T took the hit publicly and are throwing resources at the problem. Mid-market carriers operating with tighter budgets might face a gap between what’s mandated and what they can operationalize by the deadline. That’s not cynicism, it’s just how these things tend to play out.

What’s almost certain is that architects designing new network management systems, whether for telecom or for enterprise infrastructure that touches telecom systems, need to build with these mandates in mind now rather than later. Default-deny segmentation. Encryption at every interface. Comprehensive logging and alerting. Vulnerability management with aggressive timelines. These aren’t novel ideas. They’re table stakes now, and they’re going to be auditable.

The Salt Typhoon breach forced a correction that should have been architectural practice years ago. If you’re building systems in 2025 that still assume the internal network is trustworthy, you’re not just behind schedule. You’re building toward a compliance violation. The interesting work right now is figuring out how to implement these requirements well, not how to avoid them.

What’s your current friction point with legacy architecture and compliance requirements? I’d genuinely like to hear what’s actually blocking modernization in your environment. Real-world constraints beat theoretical best practices every time.

Continue Reading

Claude 3.7 Sonnet’s Extended Thinking Mode: When Your AI Needs to Actually Think Before Speaking

The Thinking Layer That Changes the Game

When Anthropic released Claude 3.7 Sonnet in February 2025, they didn’t just ship a faster model. They shipped something philosophically different: a version of Claude that could spend serious computational cycles reasoning through a problem before committing to an answer. Extended thinking mode lets the model configure token budgets up to 128K tokens dedicated purely to internal reasoning, with that deliberation happening invisibly before you ever see the output. If you’ve spent years watching AI models confidently hallucinate their way through complex problems, this distinction matters.

The practical implication is straightforward: you’re trading latency for coherence. The model gets to work through multi-step reasoning chains, backtrack on dead ends, and build toward stronger conclusions before presenting them to you. It’s the difference between someone blurting out an answer versus someone who thinks for thirty seconds and gives you something thoughtful. Except here, that thirty seconds is actually 15 to 40 seconds of added latency depending on your token budget, and it happens server-side before you get your response.

The Performance Jump That Matters for Real Work

Let’s talk numbers because they tell the story better than marketing speak ever could. On SWE-bench Verified leaderboard, Claude 3.7 Sonnet landed at 70.3% accuracy on autonomous coding tasks at release. That’s not just ahead of GPT-4o. It’s meaningfully ahead. For teams building production systems that need to handle code generation, debugging, or architectural decisions, this isn’t background noise. This is the kind of performance gap that changes what you can reasonably expect an AI system to accomplish without human verification.

What makes this particularly interesting is that extended thinking mode is driving much of that capability lift. The model isn’t smarter in some absolute sense. It’s more methodical. It gets to consider multiple solution paths before settling on one. On coding tasks especially, this matters. Code review isn’t about flashy first answers. It’s about catching edge cases, thinking through dependencies, and avoiding the kind of subtle bugs that you only find at 3 AM in production.

The Cost-Versus-Latency Tradeoff That Will Define Your Architecture

Here’s where I need to be direct: extended thinking is not free, and the costs scale harder than you probably want. Developers on the Anthropic forum have reported 2-3x higher per-task costs when extended thinking is enabled versus running in standard mode. That’s not a rounding error. That’s the difference between a feature being “nice to have” and a feature being “we need to think hard about where we use this.”

Add to that the latency hit. 15 to 40 seconds of additional delay might sound manageable until you remember that you’re probably calling this from a service with its own SLA requirements, which has a frontend waiting for a response, which has users waiting for that frontend. The latency stacks. The costs compound. This is why you can’t just enable extended thinking globally and call it a day. You need to be surgical about it.

The smart play is to treat extended thinking mode as a specialized tool, not the default behavior. Use it for genuinely hard problems. Use it when the cost of a wrong answer exceeds the cost of waiting and spending more tokens. Use it for batch processing where latency is less critical. Skip it for customer-facing requests where sub-second response times matter. This is the kind of architectural thinking that separates well-designed AI pipelines from expensive, broken ones.

Getting Started: Where Extended Thinking Actually Makes Sense

If you’re building on top of Claude 3.7 Sonnet and wondering where to start with extended thinking, begin here: identify one process in your pipeline that currently fails or requires human review. Not the most latency-critical one. Not the highest volume one. Pick something that’s expensive when it goes wrong, happens in batch, or currently requires a human to verify the output.

Maybe you’re generating test cases for edge cases in your system. Maybe you’re doing architectural design reviews for code submissions. Maybe you’re synthesizing patterns from logs or traces. These are places where spending an extra 20 seconds and using more tokens actually pays for itself, because the alternative is a human spending 5 minutes or a bug making it to production. Start there. Measure the quality improvement and the actual cost. Then expand methodically.

The good news is that you don’t need to roll your own infrastructure. AWS Bedrock integrated Claude 3.7 Sonnet within weeks of release, making it the fastest Anthropic model to reach general cloud availability. That means if you’re already on AWS, you can start experimenting without building new infrastructure. Configure your token budgets, test different reasoning depths, and measure the actual impact on your workload before committing to architectural changes.

What This Means for the Next Phase of Production AI

Extended thinking mode represents a shift in how we should think about AI systems in production. For years, the game was about raw speed and inference cost per request. Get the answer fast, get it cheap, move on. Extended thinking mode says: sometimes the right answer matters more than the fast answer. Sometimes you want the system to actually deliberate.

This changes what problems become tractable for AI. It makes certain classes of work that currently require humans potentially automatable. It also makes cost tracking more complex and latency budgeting harder to reason about. It’s not disruptive in the flashy sense. It’s disruptive in the architectural sense. It means you need to think differently about where AI fits into your system.

If you’ve been on the sidelines waiting for AI capabilities to mature enough to handle genuinely difficult problems, this is worth a serious look. Start small. Measure everything. Figure out where the thinking time actually saves you money or risk. Then build from there. The teams that get this right won’t be the ones who treat extended thinking as a magic bullet. They’ll be the ones who understand the tradeoffs deeply enough to use it exactly where it matters.

Continue Reading

Aurora DSQL: The Database Nobody’s Asking the Right Questions About

The Quiet Launch That Changed Everything

If you weren’t paying close attention during re:Invent 2024, you might have missed one of the more consequential database announcements AWS has made in years. Aurora DSQL arrived with the kind of understated confidence that only comes from years of refinement behind closed doors. Not a brand new concept. Not vaporware. Just a distributed SQL database that promised 99.999% availability, active-active multi-region writes, and zero infrastructure management. The kind of thing that makes you nod and think “okay, sure” until you actually start digging into what it means operationally.

What struck me most wasn’t the feature set. It was the adoption curve. By re:Invent 2025, over 40,000 customers had already migrated workloads to Aurora DSQL within that first year. For a database service, that’s not incremental growth. That’s the kind of velocity you see when the problem being solved is visceral enough that people will upend their infrastructure to address it. Multi-region consistency at scale has been the kind of architectural problem that keeps senior engineers awake, and suddenly there was a managed service offering to handle it.

The Pricing Reality Check That Everyone Missed

Here’s where the conversation gets honest. The headline pricing looks sensible on the surface: $0.25 per million read request units, $1.00 per million write request units. Clean. Simple. Mathematical. The kind of pricing structure that makes sense when you’re comparing it to traditional Aurora on paper. But then you run actual workloads through it.

Early adopter reports started trickling through senior engineering channels around mid-2025. The pattern was consistent enough to be troubling: real-world Aurora DSQL bills were running 40 to 60 percent higher than equivalent Aurora Serverless v2 workloads for comparable traffic patterns. Not catastrophically higher. Not “shut it down” higher. But high enough that you start asking hard questions about what you’re actually paying for. The distributed consistency guarantees carry a computational overhead. The cross-region coordination infrastructure has to live somewhere. The request unit accounting doesn’t quite map one-to-one with traditional Aurora because the work being performed at the database layer is fundamentally different.

I spent a week with one customer last quarter who had migrated a 15 terabyte read-heavy workload to Aurora DSQL expecting cost neutrality. The bill came back 52 percent higher. The workload ran faster. The latency profile improved. The multi-region consistency guarantee eliminated an entire category of data reconciliation jobs they’d been running as cron tasks. Still, the number on the invoice was undeniably larger. That’s the conversation AWS doesn’t lead with, and it’s the one you need to have before you commit infrastructure.

Why Enterprises Are Actually Making This Trade

The adoption numbers only make sense when you understand what’s actually driving the migration. It’s not pure technical elegance, though that exists. It’s regulatory. The EU’s data sovereignty requirements have become genuinely complex for global enterprises. Gartner’s 2025 Cloud Database Management Systems report captured something important: distributed SQL adoption among enterprise customers grew 38 percent year-over-year, driven largely by compliance requirements under new EU regulations. When your regulatory framework demands that certain data never leave a specific geographic region while simultaneously requiring real-time consistency across multiple regions, you’re essentially forced into a corner.

Aurora DSQL addresses that corner directly. Multi-region active-active writes mean you can partition data geographically while maintaining transactional guarantees. You’re not building eventual consistency workarounds. You’re not managing complex replication pipelines. You’re not hiring another database engineer to maintain the infrastructure. That’s worth paying a premium for, especially when the alternative is either violating compliance requirements or building a custom distributed system that costs more in engineering time than the premium ever would.

The Gartner Cloud Database Management Systems report noted that this trend isn’t reversing. If anything, it’s accelerating as regulatory frameworks tighten globally. That 38 percent year-over-year growth in distributed SQL adoption isn’t a blip. It’s a structural shift in how enterprises think about database architecture.

The Latency Question That Matters More Than People Admit

Here’s where I get genuinely curious, and where I think the conversation needs to mature beyond marketing slides. CockroachDB published a benchmark in late 2025 comparing Aurora DSQL against their own distributed SQL platform under equivalent multi-region test conditions. The results were methodologically sound and genuinely interesting. Aurora DSQL averaged 8 milliseconds for cross-region writes. CockroachDB averaged 6 milliseconds. Two milliseconds doesn’t sound like much until you’re running 50,000 transactions per second and suddenly you’re looking at meaningful differences in throughput and tail latencies.

The question isn’t whether two milliseconds matters in the abstract. The question is whether it matters for your specific workload. For most OLTP applications, no. For high-frequency trading platforms, fintech settlements, or real-time gaming state machines, absolutely yes. The benchmark also highlights something worth sitting with: Aurora DSQL isn’t magically better at distributed systems. It’s a competent implementation making reasonable trade-offs. Finding that it’s slightly slower at cross-region operations than purpose-built distributed SQL databases shouldn’t surprise anyone. AWS is optimizing for breadth and ease of use. Specialized vendors are optimizing for specific performance profiles.

What matters is whether the trade-offs align with your requirements. Check the AWS Aurora DSQL documentation and pricing against your actual workload patterns. Run proof-of-concept tests. Measure what actually happens when you stress your specific use case. Don’t accept benchmark results as gospel. Don’t accept pricing tier estimates as representative. Measure your own reality.

The Conversation We Should Be Having

Aurora DSQL is a genuine inflection point in how cloud databases are evolving. Not revolutionary. Evolutionary in exactly the right way. The service is mature enough to handle production workloads for thousands of customers. The pricing is sustainable if you understand what you’re paying for. The compliance value proposition is real and increasingly essential.

What I keep coming back to is what happens next. Regulatory frameworks are tightening. Multi-region architectures are becoming baseline expectations rather than edge cases. Customers are getting more sophisticated about actual costs versus promised costs. So does “simple, managed, distributed SQL at scale” eventually become a commodity? Do the latency and cost trade-offs compress as the technology matures? Does someone eventually build something that makes all of this look as quaint as worrying about database sharding looks now?

If you’re evaluating Aurora DSQL, I’d genuinely like to hear what you’re finding. What’s working. What’s not. Where the pricing surprises you. Where the latency profile doesn’t meet expectations. Where the compliance value actually justified the engineering migration. The sales narrative is clear. The reality is messier and more interesting. That’s always where the good conversations start.

Continue Reading

Vibe Coding Is Eating Junior Dev Hiring — And the Consequences Are Starting to Show Up in Production

The Term That Went Viral, and What It Actually Means

A few months back, Andrej Karpathy posted something on X that crystallized what a lot of senior engineers had been observing quietly in Slack channels and code review threads. He called it “vibe coding” — the practice of treating large language models as your primary code-generation engine while you shift into a directorial role, essentially prompting your way through features rather than writing them yourself. The post landed hard because it named something that previously existed in a fuzzy gray area, discussed in whispers among architects worried about team dynamics.

Vibe Coding Is Eating Junior Dev Hiring — And the Consequences Are Starting to Show Up in Production

Within weeks, the term exploded across developer communities. Junior developers started building their entire skill set around prompt engineering rather than algorithmic thinking. Some mid-level engineers restructured their workflow entirely around LLM output. The viral moment wasn’t surprising. It offered a seductive narrative: write less, move faster, delegate the mechanical parts to the AI. Except the second-order effects are now showing up in the places where seductive narratives always show up: production logs, on-call pages, and in the quiet conversations between engineering leads and their managers about why code quality metrics are drifting.

If you want to understand the specific mechanics of what Karpathy was describing, Andrej Karpathy’s Original Vibe Coding Post captures the concept with precision. But the real story isn’t in that single post. It’s in what happened after.

Illustration for Vibe Coding Is Eating Junior Dev Hiring — And the Consequences Are Starting to Show Up in Production

Speed Gains and the Bugs That Follow

Here’s where the data gets interesting, and also where I want to be careful not to strawman AI-assisted development. A 2025 survey from Uplevel analyzed engineering teams using AI coding tools at scale and found that time-to-PR dropped by 40 percent. That’s legitimately impressive. You can quantify that. Your sprint velocity goes up, your deployment frequency increases, and your management chain sees the metrics they care about moving in the right direction.

Then you look at the 30-day post-merge window. Post-merge bug reports increased by 41 percent. That’s not a rounding error. That’s not noise. That’s a pattern. The bugs aren’t appearing during CI, they’re making it through, getting deployed, and hitting users. When I say making it through, I mean slipping past your test suites, your code reviews, and your linting rules. Uplevel Developer Productivity Research digs deeper into these patterns if you want specifics, but the headline is clear: you’re trading stability for throughput.

Stripe’s engineering team did internal audits on this exact problem and documented what they found. The errors weren’t random. They were systematic. Off-by-one errors that slipped through bounds checking. Error-handling patterns that looked syntactically correct but didn’t actually catch the edge cases they were meant to catch. These are the kinds of bugs that senior engineers catch in code review if they’re paying attention, but they require the kind of attention that becomes harder to maintain when pull request volume is up 40 percent and your team is trained to move fast.

The Junior Developer Squeeze and What It Means for Your Industry

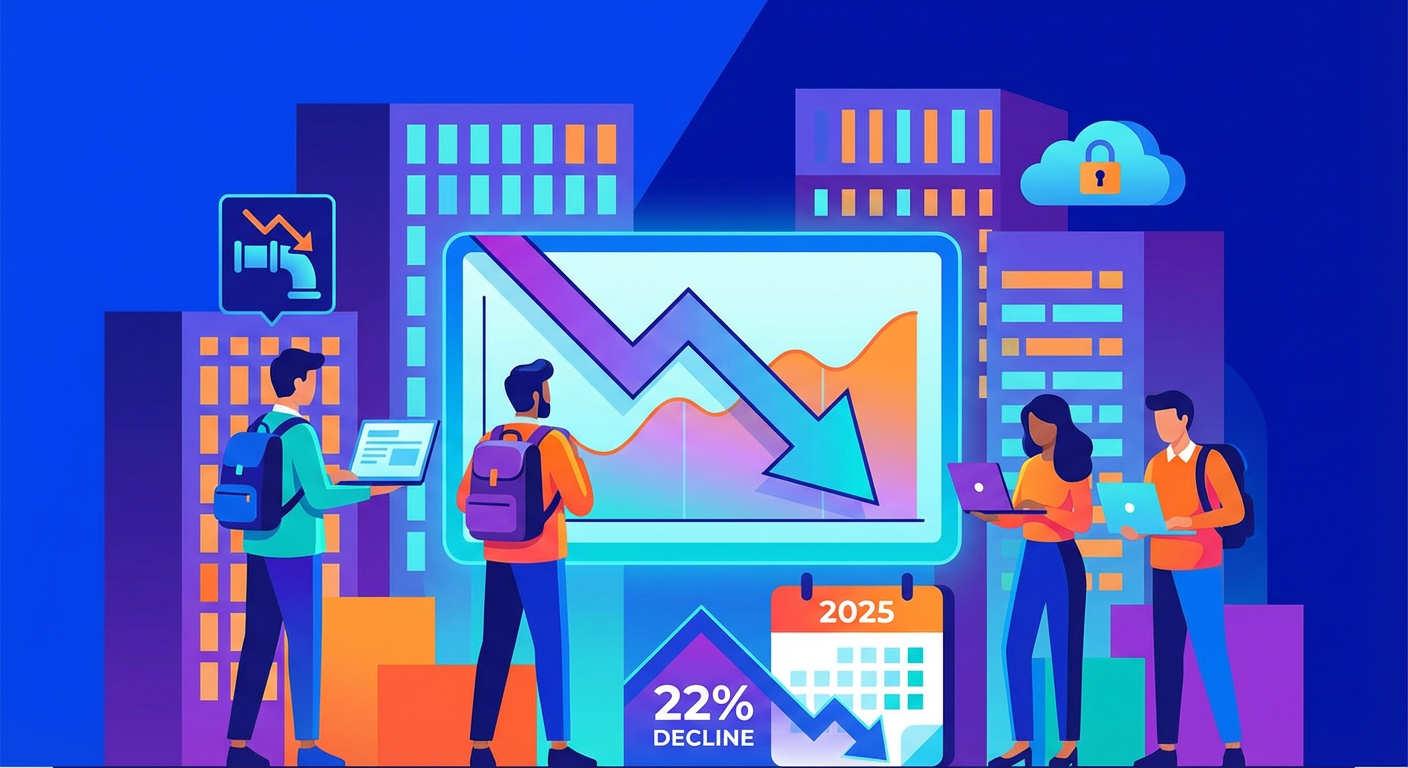
The third piece of this story is harder to ignore because it’s affecting people directly. Job postings for entry-level software engineering roles at companies with over 1,000 employees declined 22 percent year-over-year in 2025. That’s according to Revelio Labs data, and it correlates almost perfectly with the timeline of vibe coding adoption across the industry.

Think about what that means for a moment. Companies got faster with AI-assisted development. They needed fewer junior developers to hit their velocity targets. So they stopped hiring junior developers. That’s a rational short-term business decision that creates a long-term structural problem. You’re not just reducing hiring. You’re cutting off the pipeline of people who learn software engineering fundamentals in a production environment, with mentorship and real feedback loops. You end up with a generation gap where mid-level engineers exist but junior engineers don’t, and when your senior engineers retire or move to startups or just get tired of debugging AI-generated code, there’s nobody coming up through the ranks who actually understands how systems are built from first principles.

I’ve worked at enough companies to know this isn’t some abstract future problem. This is happening now. It’s affecting hiring decisions, team composition, and the kind of technical debt you’re accumulating without realizing it.

Code Complexity and the Invisible Tax

Here’s the part that keeps me up at night, and I mean that literally. I’ve had several 3 AM debugging sessions prompted by this exact phenomenon. A 2025 IEEE Software editorial cited preliminary data from three large tech companies showing that codebases where more than 50 percent of commits were AI-assisted had measurably higher cyclomatic complexity scores within 12 months of adoption.

Cyclomatic complexity isn’t just a number on a dashboard. It’s a proxy for how hard your code is to understand, modify, and reason about. When you’re prompting an LLM to generate code, you get output that works. It passes your tests. But it doesn’t necessarily reflect the simplest solution. It reflects what the model predicts is likely given the training data. Sometimes that’s elegant. Often it’s not. Sometimes it’s three nested conditionals when one would do. Sometimes it’s defensive code handling cases you don’t actually need to handle. It accumulates. Every developer who touches that code adds their own layer of AI-generated defensive patterns, and suddenly you’ve got a codebase that’s technically correct but structurally Byzantine.

The tax comes due when you need to modify that code. When business requirements change. When you need to scale it. When you need to onboard someone new. The time you saved on the first pass gets repaid with interest during refactoring, debugging, and maintenance cycles that stretch over months instead of weeks.

What Actually Matters Going Forward

I want to be clear about something: AI-assisted coding isn’t going away, and it shouldn’t. Copilots and LLMs are genuinely useful tools. I use them regularly. The difference between using a tool well and letting a tool use you comes down to one thing: understanding. If you can’t explain why the AI generated a particular solution, if you can’t reason about its correctness from first principles, then you’re not using the tool. The tool is using you, and you’re the bottleneck that doesn’t realize it yet.

For junior developers, this is a career inflection point worth thinking about clearly. The developers who matter in five years won’t be the ones who got good at prompting. They’ll be the ones who got good at thinking. Who understand systems. Who can spot the off-by-one error in the LLM output before it ships. Who can refactor a complex codebase because they understand complexity. The AI isn’t going to teach you that. Your team needs to.

For senior engineers and technical leads, this is a question about what you’re optimizing for. Speed or stability. Growth or maintenance burden. Short-term metrics or long-term capability. You can have fast code or you can have good code. With discipline and the right review culture, you can sometimes have both. But not if you’re treating AI output as a substitute for thinking.

The interesting problems in software engineering right now aren’t about generating code faster. They’re about maintaining code well. About building teams that can sustain velocity without trading away quality. About protecting junior developers’ learning paths in an environment where the industry is actively trying to automate those paths away. If you’re dealing with these tensions at your organization, I’d genuinely like to hear what you’re seeing. Drop a comment or send a note.

Continue Reading