The Next Five Years of Stack Security: Why Your Container Registry Is the New DMZ

The Signal: Attack Vectors Are Moving Up the Stack

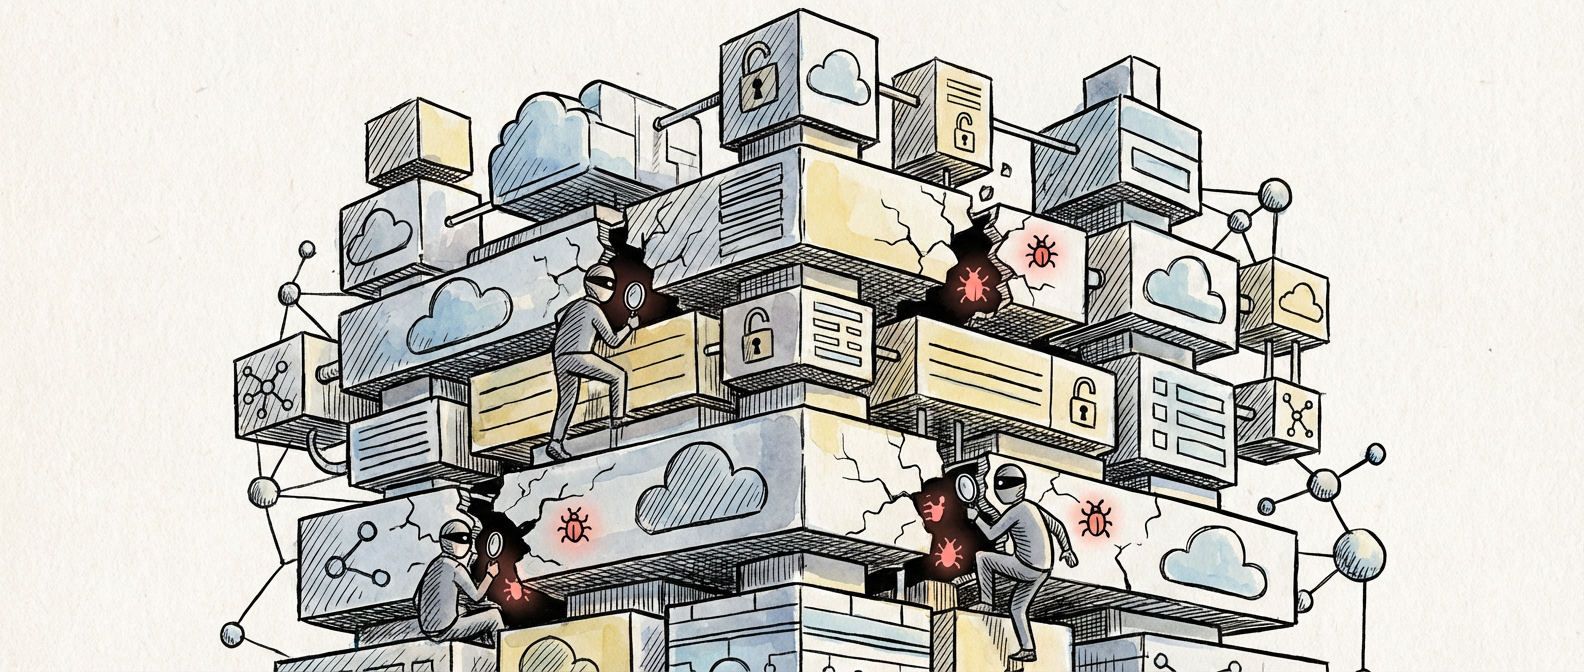
After watching three decades of security theater, I’ve learned to tell the difference between daily panic and real paradigm shifts. Right now, we’re seeing something that should make every engineering leader uncomfortable: attackers have figured out that breaking into production is easier when you own the build pipeline.
The Next Five Years of Stack Security: Why Your Container Registry Is the New DMZ

The numbers tell a clear story. Supply chain attacks jumped 742% in 2022, but that statistic doesn’t capture the sophistication we’re seeing. SolarWinds was just the opening act. Today’s attackers skip the SSH brute-forcing and buffer overflow hunting. Instead, they submit pull requests to your dependencies and let your CI/CD pipeline do the work for them.

This has moved past theoretical risk. I’ve seen organizations discover malicious packages sitting in their private registries for months, quietly stealing API keys and database credentials. When a compromised npm package or Docker base image gets loose, the damage makes our old firewall-and-perimeter fears look quaint.

Container Registries: The New Crown Jewels

Security teams love talking about “defense in depth,” but most still operate like it’s 2005. They’re hardening the wrong surfaces while the real action happens in infrastructure that didn’t exist when their threat models took shape. Your container registry isn’t just another piece of infrastructure. It’s how everything your organization runs gets distributed.

Here’s what keeps me up at night: the average enterprise pulls base images from public registries without verification, adds dependencies from package managers they don’t control, then pushes everything to production registries that engineering teams trust completely. That trust is the weakness. When your Kubernetes cluster pulls an image tagged as “latest,” it’s running a binary built from sources you’ve never checked, using dependencies you’ve never reviewed.

Attackers have done the math. Why waste time on sophisticated zero-days when you can compromise a popular base image and wait for targets to update themselves? Supply chain attacks scale better than any traditional vector. One compromised image reaches thousands of production environments.

The Serverless Mirage: New Abstractions, Old Problems

Serverless and edge computing promise to eliminate entire categories of security headaches. No servers to patch, no operating systems to harden, just pure business logic running in someone else’s carefully managed sandbox. It sounds great, especially if you’re tired of midnight security patches.

Reality is messier. Serverless doesn’t eliminate security concerns, it just moves them around. Your Lambda function still runs code built from dependencies, and those dependencies carry the same supply chain risks as any traditional app. The difference is that serverless environments often have weaker visibility and logging, so detection gets harder.

Edge computing makes things worse. When your code runs on thousands of edge nodes worldwide, each with different security postures and update schedules, the attack surface multiplies fast. A vulnerability in edge runtime or a compromised edge node can mess with traffic patterns across entire regions. We’re basically rebuilding distributed systems security problems at internet scale.

But here’s what I find interesting: serverless constraints actually force better security practices. When you can’t SSH into a server to fix things, you have to build security into the deployment pipeline. When function cold starts hurt user experience, you trim dependencies and reduce attack surface. The best serverless teams I know have better security hygiene than traditional infrastructure teams, precisely because the platform forces discipline.

AI-Generated Code: The Security Wild West

Every engineer is now a full-stack developer, and every full-stack developer is now a security engineer, whether they realize it or not. Code generation through AI tools means vulnerabilities get introduced faster than ever, often by developers who don’t have the security background to spot them.

I’ve audited codebases where 40% of the application logic came from AI suggestions. That includes authentication flows, database queries, API integrations. The code usually works perfectly in testing but carries subtle vulnerabilities that only show up under specific conditions. SQL injection patterns that would jump out in hand-written code get buried in generated functions that look clean and professional.

The signal versus noise problem is brutal here. Static analysis tools can’t keep up with AI-generated code patterns. Traditional code review breaks down when you’re reviewing AI suggestions that span hundreds of lines. Teams ship faster than ever, but with security debt that builds up invisibly.

The same AI creating these problems might solve them though. I’m tracking several projects using language models to audit code for security vulnerabilities in real-time, giving context-aware feedback during development. Early results suggest AI can catch entire categories of vulnerabilities that human reviewers miss, especially in generated code.

The Path Forward: Security That Scales with Reality

The next five years will separate organizations that adapt their security posture from those that stick with perimeter-based thinking. The winners will treat security as a distributed system problem, not a checklist problem. They’ll invest in supply chain verification, build security into their CI/CD pipelines, and create feedback loops that make security violations expensive to ignore.

Practical steps matter more than grand strategies. Start with dependency pinning and verification in your container builds. Implement binary attestation for your deployment pipelines. Build security scanning into your development workflow so vulnerabilities get caught before they reach production. These aren’t flashy solutions, but they address the actual attack vectors we’re seeing.

The organizations getting this right recognize security as an engineering problem, not a policy problem. They’re building systems that make secure choices the default choices, rather than depending on developer discipline or security team reviews. They’re treating security tooling like first-class engineering infrastructure, with the same reliability and performance requirements as any other system that matters.

What patterns are you seeing in your own stack? I’m curious about how teams are handling supply chain verification and whether AI-assisted security review actually works in practice. Drop your war stories in the comments.
Continue Reading

Why Your API Will Fail (And the Three Patterns That Saved Mine)

The Midnight Revelation

It was 2:47 AM when I realized our payment API was fundamentally broken. Not broken in the “server’s down” sense, but broken in the “we designed ourselves into a corner and now every client integration looks like a crime scene” sense. The Slack channel was lighting up with frustrated frontend developers trying to figure out why updating a user’s payment method required seventeen different endpoint calls and a PhD in our internal data model.

That night taught me something important: good API design isn’t about following REST principles or having perfect OpenAPI documentation. It’s about understanding that your API is a conversation between your system and everyone who has to work with it. And like any conversation, it can either be elegant or excruciating.

The Command Query Responsibility Segregation Wake-Up Call

The first pattern that saved us was CQRS, though not in the way you might expect. We weren’t dealing with complex event sourcing or massive scale issues. Our problem was simpler and more annoying: we had conflated reading data with writing data in ways that made both operations unnecessarily complex.

Our original user endpoint was a classic example of API design gone wrong. GET /api/users/123 returned a massive object with nested relationships, computed fields, and UI-specific formatting. The same endpoint that handled updates expected a completely different structure. Developers had to perform mental gymnastics to figure out what subset of the response could actually be sent back for updates.

The fix was splitting our concerns cleanly. Read operations got their own endpoints optimized for specific use cases: /api/users/123/profile for basic info, /api/users/123/preferences for settings, /api/users/123/activity for dashboards. Write operations became focused command endpoints: POST /api/users/123/update-email, POST /api/users/123/change-password. Suddenly, client code went from incomprehensible to obvious. The 3 AM debugging sessions became a memory.

The Facade Pattern (Or How I Stopped Worrying and Learned to Love Abstraction)

The second revelation came when I watched a junior developer try to implement a “simple” feature: displaying a user’s recent order history with payment status. What should have been straightforward turned into a choreographed dance across six different microservices. Orders service, payments service, shipping service, inventory service, user service, and promotions service all had to be called in the right sequence with the right parameters.

We implemented a facade pattern that created higher-level endpoints focused on business capabilities rather than internal service boundaries. Instead of forcing clients to understand our microservice architecture, we gave them /api/users/123/order-summary and /api/orders/456/full-details. These facade endpoints handled the internal complexity, data aggregation, and error handling. They became the interface between “what the business needs” and “how we implemented it internally.”

The performance impact was negligible because we were already making those calls anyway. The developer experience impact was enormous. New team members could build features without needing a systems architecture degree. Client applications became more resilient because they had fewer integration points to fail.

Versioning Strategy That Doesn’t Make You Want to Quit

The third pattern emerged from a crisis that many growing companies face: how do you evolve your API without breaking everything that depends on it. We had learned this lesson the hard way when our mobile app stopped working after what we thought was a “minor” API update. Turns out, removing a field that “nobody uses anymore” breaks things in spectacular ways.

Our solution was a practical versioning strategy that balanced evolution with stability. We used URL versioning (/api/v2/users) for major changes and feature flags for incremental improvements. The key insight was treating API versions like product releases, not code releases. Version 2 wasn’t “the new version,” it was “the version with breaking changes to user management and order processing.”

We maintained two versions at the same time for a planned deprecation period. The older version got security updates and critical bug fixes, but new features went into the current version. We provided clear migration guides with code examples, not just documentation changes. Most importantly, we automated compatibility testing between versions so we knew immediately when we were about to break existing integrations.

The Patterns That Stick

Three years later, these patterns have become the foundation of how we design new APIs. CQRS keeps us honest about separating what we read from what we write. Facade patterns let us evolve our internal architecture without punishing our clients. Thoughtful versioning means we can ship new features without creating support nightmares.

But the real lesson wasn’t about specific patterns. It was about shifting perspective from “what does our system need” to “what conversation do we want to have with the people who use this.” Your API is not just a technical interface. It’s a contract, a promise, and sometimes the difference between a developer’s good day and their very bad day.

What patterns have you found essential in your own API design work? And more importantly, what disasters have taught you the most about what not to do?

Continue Reading

Database Performance in 2025: Beyond Index Tuning and Into the Adaptive Future

The Evolution Beyond Traditional Optimization

After two decades of wrestling with databases that buckle under production load at the worst possible moments, I’ve watched the performance optimization world shift from art to science to something approaching magic. The old playbook of adding indexes, tweaking query plans, and throwing more RAM at the problem isn’t disappearing, but it’s becoming the baseline rather than the solution. What’s emerging is a new category of adaptive systems that optimize themselves faster than any human DBA ever could.

Database Performance in 2025: Beyond Index Tuning and Into the Adaptive Future

The signal here is unmistakable: machine learning isn’t just coming to database optimization, it’s already here and quietly revolutionizing how systems handle performance bottlenecks. Amazon’s RDS Performance Insights now predicts query degradation before it happens. PostgreSQL 17 introduced adaptive query execution that learns from previous runs. Oracle’s Autonomous Database adjusts itself continuously without human intervention. These aren’t experimental features anymore. They’re production-ready capabilities that are fundamentally changing what it means to optimize database performance.

The big question is how far this automation will extend. Will we see databases that automatically partition tables based on access patterns? Systems that predict and pre-cache data before applications even request it? The technology foundations are already in place. What we’re waiting for is better modeling algorithms combined with the computational power to run them at the speed of business operations.

Adaptive Indexing: When Databases Learn Your Patterns

Traditional database indexing has always been a game of educated guesses followed by painful production discoveries. You analyze your queries, create indexes based on WHERE clauses and JOIN conditions, and hope you’ve covered the 80% case. Then a marketing campaign launches, user behavior shifts, or someone adds a seemingly innocent ORDER BY clause, and your carefully crafted index strategy becomes a performance liability overnight.

The breakthrough emerging now is adaptive indexing systems that monitor query patterns in real-time and automatically adjust index configurations. Microsoft’s SQL Server 2022 introduced automatic index management that creates missing indexes but also drops unused ones that are consuming maintenance overhead. More sophisticated is the work happening in academic circles around learned indexes, where machine learning models replace traditional B-tree structures for specific workload patterns.

What gets me excited about this trend is the potential for databases to become truly self-optimizing. Imagine a system that notices your e-commerce database gets hammered with product searches every Black Friday, automatically creates temporary indexes for those specific query patterns, then removes them when traffic normalizes. The technology isn’t there yet for full autonomy, but the building blocks are rapidly falling into place.

What keeps me up at night is whether we’ll see workload-specific database engines that optimize themselves for particular use cases. A database that recognizes it’s primarily serving a time-series workload and automatically restructures its storage engine accordingly. Or one that detects heavy analytical queries and switches from row-based to columnar storage for affected tables. The line between database configuration and database architecture is starting to blur.

Query Execution in the Age of Prediction

Query optimizers have traditionally been reactive systems. They analyze the SQL you’ve written, consider the available indexes and statistics, estimate costs for different execution plans, and pick what seems like the best approach. This works reasonably well for stable workloads with predictable data distributions, but falls apart when dealing with skewed data, parameter sniffing issues, or queries that behave differently based on runtime conditions.

The transformation happening now is the shift toward predictive query execution. PostgreSQL’s adaptive query execution learns from previous runs of similar queries and adjusts plans based on actual performance history rather than just statistics. This is particularly powerful for parameterized queries where the same SQL statement might need completely different execution strategies depending on the parameter values. Instead of generating one plan and hoping it works for all scenarios, the optimizer maintains multiple execution strategies and chooses the appropriate one at runtime.

Oracle’s Autonomous Database takes this further with adaptive SQL plan management, which continuously monitors query performance and automatically evolves execution plans based on changing data characteristics and system load. When a query starts performing poorly, the system doesn’t wait for a DBA to investigate. It automatically tests alternative execution strategies in the background and switches to better plans when it finds them.

The possibility that has me most intrigued is cross-query optimization. What if the database could recognize that multiple concurrent queries are accessing overlapping data sets and automatically coordinate their execution to minimize I/O? Or predict that a particular analytical query will benefit from data that’s about to be cached by an upcoming OLTP workload? This level of holistic optimization would require databases to think beyond individual query performance toward overall system throughput.

Storage and Caching: The Memory Hierarchy Renaissance

The traditional memory hierarchy of RAM, SSD, and spinning disk is being disrupted by new storage technologies and intelligent caching algorithms that blur the lines between these layers. Persistent memory technologies like Intel’s Optane created a new tier between RAM and SSD with characteristics that don’t fit neatly into existing caching strategies. Meanwhile, cloud providers are introducing storage classes with different performance and cost characteristics that require more sophisticated data placement decisions.

What’s particularly exciting is the emergence of adaptive buffer pool management that goes beyond simple LRU replacement algorithms. Modern databases are starting to use machine learning to predict page access patterns and optimize cache eviction policies accordingly. PostgreSQL’s work on adaptive replacement caches and MySQL’s experiments with learned buffer pool management represent early steps toward systems that understand workload patterns at a deeper level than traditional heuristics allow.

The signal worth watching is the increasing sophistication of automatic data tiering. Amazon’s RDS now automatically moves infrequently accessed data to cheaper storage tiers, but this is just the beginning. Future systems will likely make these decisions at much finer granularities, potentially down to individual rows or even column values within rows. What has me excited is the possibility of databases that automatically distribute data across different storage media based on access patterns, cost constraints, and performance requirements without requiring explicit configuration.

Looking Forward: The Infrastructure Implications

The shift toward adaptive database systems has major implications for how we design and operate data infrastructure. Traditional capacity planning models break down when databases automatically adjust their resource consumption based on workload characteristics. Monitoring strategies need to evolve beyond tracking CPU and memory utilization to understanding the decisions that adaptive systems are making and whether those decisions align with business objectives.

The most significant change I’m tracking is the emergence of intent-based database management, where administrators specify business outcomes rather than technical configurations. Instead of tuning buffer pool sizes and checkpoint intervals, you might specify that analytical queries should complete within certain time bounds while maintaining OLTP response times below specific thresholds. The database then automatically configures itself to meet those objectives and adapts as conditions change.

What keeps me most engaged is whether we’re heading toward a future where database performance optimization becomes a solved problem. Not in the sense that databases become infinitely fast, but that the optimization process becomes so automated and effective that performance tuning shifts from a specialized skill to a business constraint specification. The database administrator role won’t disappear, but it will evolve toward defining policies and objectives rather than implementing low-level optimizations.

I’m curious about your experiences with these emerging optimization techniques. Have you experimented with adaptive query execution in your production environments? What performance challenges are you facing that traditional optimization approaches can’t solve? The intersection of machine learning and database systems is moving fast enough that sharing practical insights helps everyone stay ahead of the curve.

Continue Reading

Why Your Framework Choice Still Matters: A Deep Dive into Architecture Fundamentals

The Virtual DOM Wars Were Just the Opening Act

Remember when we all thought the virtual DOM was the final word in frontend architecture? Those halcyon days of 2015 when React evangelists proclaimed the end of direct DOM manipulation and Angular disciples countered with zone.js magic. We were so naive. The virtual DOM turned out to be less revolutionary paradigm shift and more clever optimization trick, and frankly, one that modern browsers have largely made irrelevant through their own performance improvements.

What actually matters in framework architecture runs much deeper than render optimization strategies. After spending the better part of a decade migrating codebases between frameworks, debugging hydration mismatches at ungodly hours, and explaining to product managers why “just switching to the hot new thing” isn’t a two-week sprint, I’ve learned that the real architectural differences lie in three fundamental areas: state management philosophy, component lifecycle approaches, and compilation strategies.

These aren’t sexy topics for conference talks, but they’re the decisions that will determine whether your application gracefully scales to 100,000 lines of code or becomes the kind of legacy system that makes senior engineers update their LinkedIn profiles. Let’s examine what actually differentiates these frameworks at an architectural level.

State Management: The Philosophical Divide

React’s unidirectional data flow isn’t just a pattern. It’s a philosophical statement about how applications should be reasoned about. When Facebook’s engineers designed React, they were solving a specific problem: the cascading update nightmare that plagued their chat system. Their solution was to make state updates explicit and traceable, even if it meant more boilerplate. This architectural decision ripples through everything else in the React ecosystem.

Vue takes a more pragmatic approach with its reactivity system. Under the hood, Vue 3’s Proxy-based reactivity is genuinely elegant, automatically tracking dependencies and updating components when their reactive dependencies change. It’s the kind of solution that makes you appreciate good API design. But here’s the thing that Vue advocates don’t always mention: this reactivity system creates implicit dependencies that can be harder to debug when things go wrong. You’ll spend less time writing boilerplate and more time with the Vue DevTools trying to understand why that computed property isn’t updating.

Angular’s dependency injection system represents yet another philosophical approach. It treats your entire application as a graph of services, with components as relatively thin presentation layers. This works brilliantly for enterprise applications where you need deep testability and modular architecture. It also means you’ll write more TypeScript decorators than you ever thought possible, and junior developers will spend their first month just understanding how the DI container resolves dependencies.

Svelte sidesteps much of this complexity by moving state management decisions to compile time. When you write `$: doubled = count * 2`, the Svelte compiler generates efficient update code that runs only when `count` changes. No virtual DOM diffing, no reactivity system overhead, just surgically precise updates. The trade-off? You’re locked into Svelte’s compilation model, and good luck trying to integrate with libraries that expect traditional JavaScript objects.

Component Lifecycles: When Simple Isn’t

React’s component lifecycle went through its own evolutionary journey. From the class component days of `componentDidMount` through the hooks revolution. Hooks represent one of the most successful API redesigns in frontend history, turning component lifecycle into a composable system. The `useEffect` hook alone handles what used to require three separate lifecycle methods, and custom hooks let you extract and reuse stateful logic in ways that were impossible with class components.

But useEffect’s dependency array is where many React applications go to die. I’ve seen production bugs caused by missing dependencies that only surface under specific user interaction patterns. The React team’s solution was to create an ESLint rule that catches most of these issues, but it’s telling that they needed tooling to make their core lifecycle API safe to use.

Vue’s composition API borrowed heavily from React hooks but with one important difference: Vue’s reactivity system automatically tracks dependencies, so you don’t need to manually specify them. When you call `watchEffect(() => console.log(count.value))`, Vue automatically knows to re-run that effect when `count` changes. It’s undeniably more convenient, though it does make the execution model less explicit.

Angular’s component lifecycle is refreshingly straightforward by comparison. `ngOnInit`, `ngOnDestroy`, and friends do exactly what their names suggest. The RxJS integration means you’ll spend more time thinking about observable streams than component lifecycles, which is either a blessing or a curse depending on your relationship with functional reactive programming.

Compilation Strategies: The Hidden Architecture

This is where framework architecture gets really interesting. Where the long-term implications of your choice become apparent. React’s approach is essentially runtime-based: the framework code ships with your application and does its work in the user’s browser. This means React applications carry the overhead of the reconciliation engine, even though most of the heavy lifting could theoretically be done at build time.

Angular pioneered the compilation approach with its Ahead-of-Time (AOT) compiler, which transforms templates and components into highly optimized JavaScript during the build process. The Ivy renderer took this even further, generating code that’s remarkably close to what you’d write by hand for direct DOM manipulation. Angular applications can be surprisingly small and fast, despite the framework’s reputation for complexity.

Svelte represents the logical extreme of the compilation approach. There’s essentially no Svelte runtime, just the compiled output of your components. This results in incredibly small bundle sizes and excellent performance characteristics. The downside is that you’re completely dependent on the Svelte compiler’s output, and debugging compiled code can be an exercise in archaeological investigation.

Vue sits somewhere in the middle, with a template compilation step that generates render functions, but still requires the Vue runtime for reactivity and component management. It’s a reasonable compromise that gives you some of the benefits of compilation without the complete framework lock-in of Svelte.

The Architecture Tax: What You Pay, What You Get

Every architectural decision comes with trade-offs, and framework choice is no exception. React’s explicit approach to state management means more boilerplate but better debuggability. Vue’s reactivity system reduces boilerplate but creates implicit coupling. Angular’s dependency injection enables powerful architectural patterns but requires significant conceptual overhead. Svelte’s compilation strategy produces optimal output but limits runtime flexibility.

The framework you choose establishes the architectural constraints your team will live with for years. React’s unidirectional data flow will influence how you structure your state management, even if you never use Redux. Vue’s reactivity system will shape how you think about component interactions, even in parts of your application that don’t use reactive data. Angular’s service-oriented architecture will determine your testing strategies and module boundaries.

These architectural differences matter more than performance benchmarks or bundle size comparisons because they determine the cognitive load your team carries. A framework that fights against your application’s natural structure will cause more long-term pain than one that’s slightly slower or produces slightly larger bundles.

Understanding these architectural differences has saved me from more bad decisions than I care to count. What aspects of framework architecture have had the biggest impact on your projects? I’d love to hear about the architectural decisions that seemed minor at the time but ended up defining entire projects.

Continue Reading

The Supply Chain Vulnerability Nobody Wants to Talk About

Your Dependencies Have Dependencies (And So Do Theirs)

I was reviewing a security audit last week when I noticed something that made me pause my coffee mid-sip. A React application with 47 direct dependencies had somehow accumulated 2,847 transitive dependencies. That’s a 60-to-1 multiplier. Each one of those packages is a potential attack vector, a maintenance burden, and a delightful little time bomb that could detonate when you least expect it.

The Supply Chain Vulnerability Nobody Wants to Talk About

The modern JavaScript ecosystem has embraced the Unix philosophy with religious fervor. Do one thing well, they say. Compose solutions from small, focused modules. It sounds elegant until you realize that displaying “Hello World” now requires downloading half the internet. The left-pad incident wasn’t an anomaly. It was a preview of what happens when we build cathedrals on foundations made of Jenga blocks.

What troubles me isn’t the dependency count itself. It’s the collective shrug we’ve given to the security implications. We’ve normalized the idea that our applications should depend on thousands of packages maintained by strangers, updated constantly, and governed by nothing more substantial than semantic versioning and good intentions. The attack surface area has grown exponentially, but our security practices still assume we’re dealing with monolithic applications written by people in the same building.

Illustration for The Supply Chain Vulnerability Nobody Wants to Talk About

Container Images Are Not Security Boundaries

Docker revolutionized deployment, but it also gave us the world’s most sophisticated method of shipping vulnerabilities directly to production. I’ve seen container images that started as 50MB Alpine Linux bases and somehow ballooned to 2GB monsters containing entire Linux distributions, multiple language runtimes, and enough outdated libraries to make a penetration tester weep with joy.

Here’s the fundamental misconception: treating containers as security isolation mechanisms. They’re not. They’re process isolation mechanisms with a thin layer of resource controls. The kernel is still shared. The network stack is still accessible. That shiny container orchestration platform you’re running? It has root access to every node, and if it gets compromised, your “isolated” workloads are about as secure as files in a shared folder.

Multi-stage builds were supposed to solve the bloat problem, but most teams use them wrong. They’ll copy their entire application source code into the build stage, install dependencies with package managers that cache everything, then selectively copy artifacts to the runtime stage while leaving behind manifests that still reference the vulnerable packages they “removed.” The result is smaller images with identical attack surfaces and worse debugging capabilities.

The solution isn’t more complex tooling. It’s going back to first principles. Minimal base images. Explicit dependency management. Regular vulnerability scanning that actually fails builds instead of generating reports that nobody reads. And please, for the love of all that is debuggable, stop running everything as root inside containers just because you can.

API Security Theater and the JWT Cargo Cult

JSON Web Tokens have become the hammer that makes every authentication problem look like a nail. Teams implement JWT-based authentication with the same enthusiasm they once reserved for microservices, usually with about the same level of understanding of the underlying complexity. The result is an ecosystem full of APIs that are simultaneously over-engineered and fundamentally insecure.

The most common mistake is treating JWTs as magic security tokens instead of what they actually are: a standardized way to encode claims that can be verified without a database lookup. Teams store sensitive data in JWT payloads, forget that the signature only prevents tampering (not reading), and implement custom verification logic that bypasses critical security checks. I’ve seen production systems that validate JWT signatures but ignore expiration times, accept tokens signed with “none” algorithms, and trust client-provided key identifiers without verification.

Rate limiting deserves special mention as the poster child for security theater. Most implementations are laughably easy to bypass. IP-based rate limiting gets defeated by proxy rotation. User-based rate limiting assumes you can identify users before they authenticate. API key-based limiting creates a single point of failure. The sophisticated attackers aren’t brute-forcing your login endpoints. They’re exploiting the business logic flaws in your password reset flows, account creation processes, and state management.

Real API security requires understanding your threat model, not copying patterns from blog posts. Authentication should happen once and be cached appropriately. Authorization should be centralized and consistently applied. Input validation should happen at the boundary, not scattered throughout your codebase. And for the record, CORS is not a security feature. It’s a browser convenience that does nothing to protect your API from server-side attacks.

The Infrastructure as Code Blindspot

Infrastructure as Code promised to bring software engineering practices to operations. What we got instead was YAML files with root-level privileges and the operational complexity of distributed systems applied to what used to be relatively simple deployment scripts. Terraform configurations have become multi-thousand-line monstrosities that nobody fully understands, managed by CI/CD pipelines with administrative access to cloud accounts worth millions of dollars.

The security implications are staggering. Cloud credentials with broad permissions get embedded in environment variables, stored in version control, and passed through build systems that log everything. State files containing sensitive configuration data get stored in S3 buckets with public read access. Terraform providers auto-approve resource changes that could expose entire network segments to the internet.

The abstraction layers haven’t helped. Kubernetes operators that manage infrastructure resources create a meta-infrastructure problem where your infrastructure definition depends on cluster state, which depends on container images, which depend on base images with their own vulnerabilities. When something goes wrong (and something always goes wrong), the debugging process requires understanding multiple abstraction layers, each with their own failure modes and security implications.

Cloud-native security tools promise to solve these problems with more automation, more scanning, and more alerts. But automation without understanding is just faster ways to make mistakes at scale. The real solution is boring: principle of least privilege, regular credential rotation, comprehensive audit logging, and humans who understand what their infrastructure actually does instead of treating it as a black box that occasionally needs YAML adjustments.

Building Systems That Fail Securely

Security vulnerabilities aren’t bugs. They’re design failures. They happen when systems behave in ways that benefit attackers instead of failing safely. The path forward isn’t more security tools or frameworks. It’s building systems with security as a fundamental design constraint, not an afterthought to be bolted on later.

This means designing APIs that fail closed instead of open. It means choosing boring, well-understood technologies over exciting new frameworks that haven’t been battle-tested. It means accepting that security often conflicts with convenience and choosing security anyway. Most importantly, it means recognizing that every dependency, every abstraction layer, and every piece of infrastructure increases complexity in ways that tools can’t automatically manage.

I’ve spent enough time debugging production incidents to know that the systems that survive are the ones designed by people who assume everything will eventually break. What specific approaches have worked (or failed spectacularly) in your experience? The comment section exists for a reason, and I’m particularly interested in hearing about the subtle vulnerabilities that only emerge under production load.

Continue Reading